
概覽
多智慧體功能可讓模型啟動多個子代理程式,協調它們平行作業,再彙整成果,產生最終回應。這項功能特別適合需要處理複雜任務,且能透過平行分工提升成效的應用程式,例如探索程式碼庫、撰寫文件或實作功能。
GPT-6.1 Sol 和所有 GPT-5.6 模型均提供多智慧體測試版功能。在應用程式中啟用前,請先查看模型頁面。
何時使用多智慧體功能
許多任務都能拆成彼此獨立的工作。單一智慧體會依序完成這些工作,多個智慧體則能平行處理。啟用多智慧體功能後,根智慧體可將工作分派給多個子代理程式,讓它們同時執行。這樣做有幾項好處:
- 平行執行。 彼此獨立的研究、分析或實作任務可同時進行,有助於縮短執行時間。
- 上下文更集中。 每個子代理程式都負責範圍明確的任務,並維護自己的上下文,可減少無關工作之間的上下文干擾,提升效能。
- 由模型協調。 根智慧體可建立子代理程式、傳送補充資訊、等待結果,並彙整出最終答案,應用程式無須自行實作協調邏輯。
當任務可以拆成多項具體且彼此獨立的工作時,多智慧體協調最能發揮作用,例如:
- 分別探索大型程式碼庫的不同部分
- 比較多份提案、文件或多種假設
- 同時研究多個資料來源
- 實作彼此獨立的元件,或撰寫彼此獨立的測試套件
- 同時調查造成故障的多種可能原因
- 同時探索解決同一問題的不同方法
增加子代理程式可能會提高 Token 用量。如果任務仰賴單一且必須依序進行的推理過程、需要頻繁寫入共用的可變狀態,或大部分時間都花在同一項緩慢的外部操作上,使用子代理程式的效益可能較小。
| 適合使用多智慧體的情況 | 適合使用單一智慧體的情況 |
|---|---|
| 工作可拆成彼此獨立且範圍明確的任務 | 每個步驟都直接依賴上一步 |
| 分開維護上下文有助於專注處理各項任務 | 任務規模小,一次短時間執行即可完成 |
| 平行探索可縮短完成任務的實際時間 | 多個智慧體會爭用同一項可變資源 |
| 比較各自得出的結果有助於涵蓋更多面向 | 需要固定且具確定性的執行圖 |
快速入門
Python 和 TypeScript 範例使用測試版 Responses SDK。透過 SDK 傳送 HTTP 請求時,請使用 client.beta.responses,並將 responses_multi_agent=v1 傳入 betas 引數。直接傳送 HTTP 請求或建立 WebSocket 連線時,請在請求或連線標頭中傳入 OpenAI-Beta: responses_multi_agent=v1。多智慧體功能在測試階段可能會變更項目的結構描述。
使用 multi_agent.enabled 在 Responses API 請求中啟用多智慧體功能。當 multi_agent.enabled 為 true 時,根智慧體就能啟動子代理程式,形成樹狀結構。子代理程式共用請求所指定的模型與可用工具,各智慧體則透過啟動子代理程式、傳送訊息和等待等基本操作來協調工作(請參閱多智慧體的運作方式)。根智慧體負責彙整子代理程式的回應,並提供最終回應。
from openai import OpenAI
client = OpenAI()
def review_pull_request(diff: str) -> str:
response = client.beta.responses.create(
model="gpt-6.1-sol",
input=(
"Review the pull-request diff below with three agents: one for "
"correctness, one for security, and one for missing tests. "
"Reconcile duplicate or conflicting findings, then return a "
"prioritized review with file and line references.\n\n"
f"<diff>\n{diff}\n</diff>"
),
multi_agent={
"enabled": True,
"max_concurrent_subagents": 3,
},
betas=["responses_multi_agent=v1"],
)
return "".join(
part.text
for item in response.output
if (
item.type == "message"
and item.agent is not None
and item.agent.agent_name == "/root"
and item.phase == "final_answer"
)
for part in item.content
if part.type == "output_text"
)max_concurrent_subagents 設定整棵智慧體樹中可同時處於作用中狀態的子代理程式數量上限。計算時包含所有後代,包括子節點、孫節點及更深層的子代理程式,但不包含根智慧體。
API 未對這項設定設下固定上限。預設值為 3,也是大多數工作負載的建議值。每次執行多智慧體任務時,樹的深度和期間建立的子代理程式總數也都沒有固定上限。
你可以新增開發者訊息,調整根模型啟動子代理程式的時機。這則訊息會補充系統為根智慧體和子代理程式注入的指示。
開發者訊息範例:
- 「只有在使用者明確要求使用子代理程式、分派任務或讓智慧體平行作業時,才啟動子代理程式。」
- 「已啟用多智慧體主動分工。如果平行作業能明顯提升速度或品質,請使用子代理程式。」
多智慧體的運作方式
Responses API 為根智慧體和子代理程式的模型提供由伺服器端執行的協調操作,以及使用這些操作的指示。根智慧體的名稱為 /root。新啟動的子代理程式使用階層式路徑,例如:
/root
├── /root/researcher
├── /root/reviewer
└── /root/reviewer/tester
多智慧體功能對子代理程式的總數或樹的深度均未設固定上限。對大多數任務而言,建議將 max_concurrent_subagents 保持為預設值 3。這項設定限制整棵樹中可同時執行的子代理程式回合數,涵蓋直接子節點及更深層的後代節點。
啟用多智慧體模式後,Responses API 會提供六種由伺服器端執行的協作操作。你可能會在輸出中看到這些操作以 multi_agent_call 項目呈現。應用程式不應執行這些操作,也不應提交其輸出。
| 操作 | 用途 |
|---|---|
spawn_agent |
建立子代理程式並指派初始任務。 |
send_message |
將訊息加入現有智慧體的佇列,不啟動新回合。 |
followup_task |
將更多工作指派給現有的非根智慧體,並啟動或恢復其回合。 |
wait_agent |
等待呼叫此操作的智慧體收到新的信箱訊息。 |
interrupt_agent |
中斷另一個智慧體目前的回合,並保留其上下文。 |
list_agents |
傳回目前的智慧體樹、各智慧體的狀態及其 last_task_message。 |
開發者自訂工具呼叫的處理方式與未啟用多智慧體功能時相同。樹中的任何智慧體都可能發出 function_call。應用程式必須執行該呼叫,並提交對應的 function_call_output。
請注意,樹中的所有智慧體都能使用 API 請求中為模型呼叫設定的工具。
在 Responses API 中使用多智慧體功能
HTTP 與 WebSocket 的效能比較
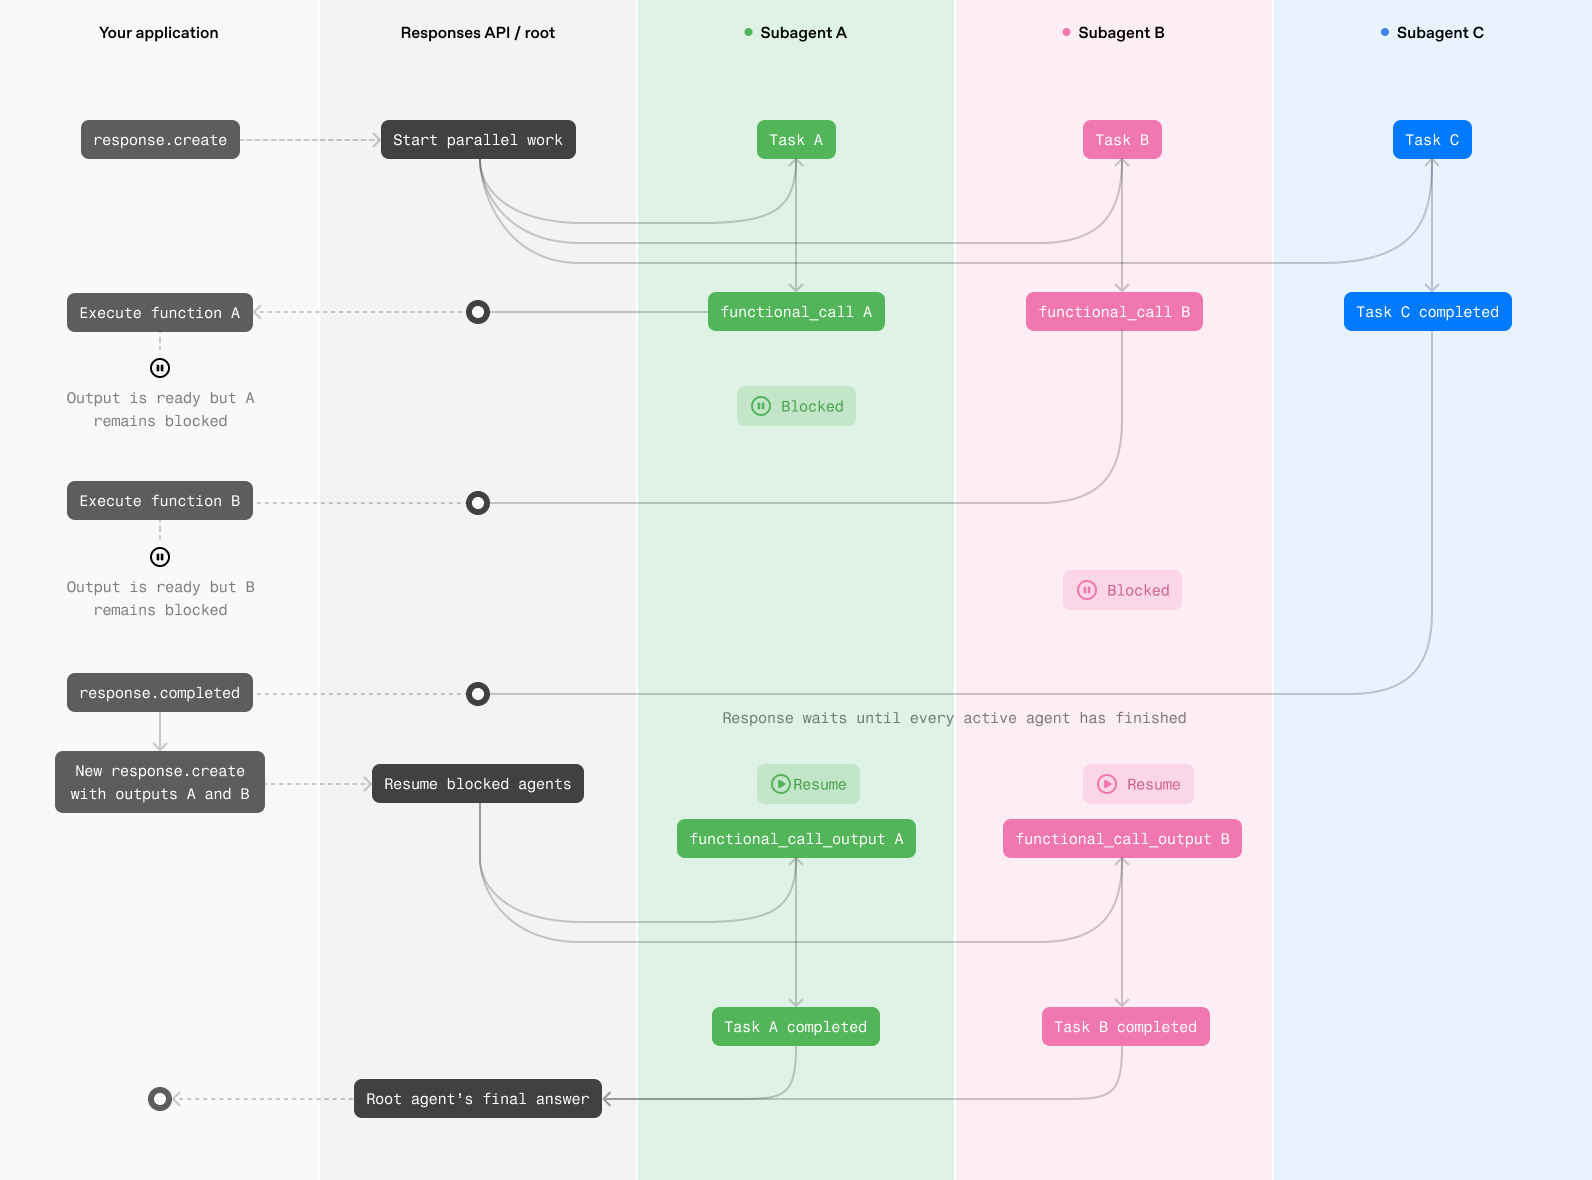
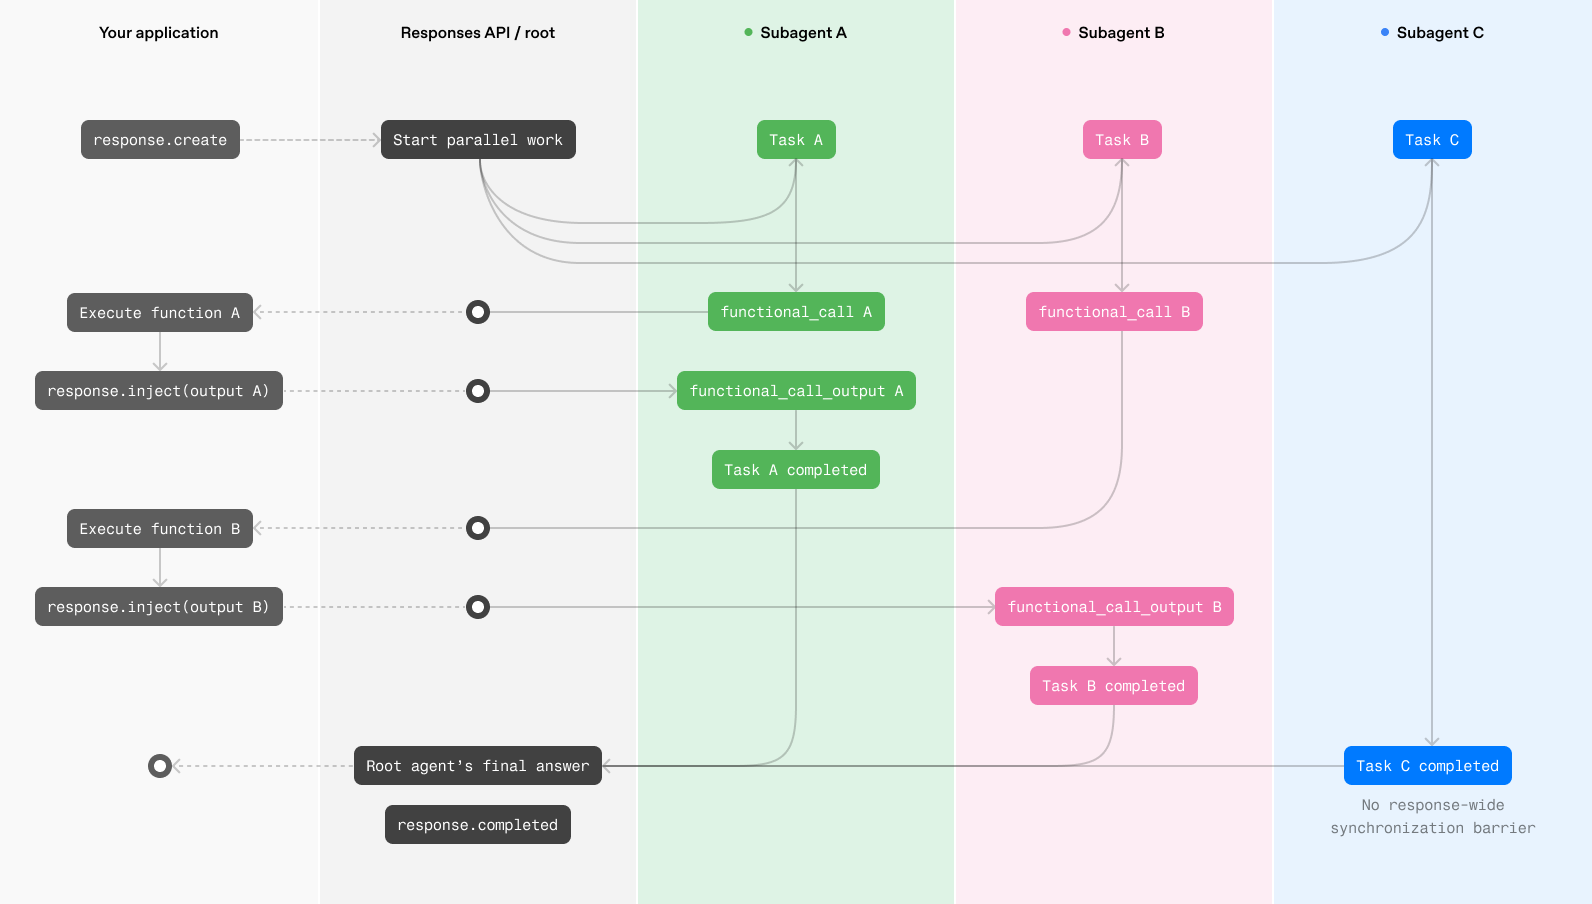
HTTP 和 WebSocket 支援相同的多智慧體功能。對於頻繁使用工具或長時間執行的工作流程,建議使用 WebSocket。透過持續連線,應用程式能在每個函式產生輸出時立即傳回結果,降低接續執行的額外成本,並縮短智慧體的等待時間。
使用 HTTP 時,必須等到每個作用中的智慧體都已完成工作或暫停以等待用戶端執行函式呼叫,回應才會完成。接著,應用程式會執行所有待處理的函式呼叫,並透過新的 Responses API 請求提交其輸出,讓暫停的智慧體繼續執行。
使用 WebSocket 時,每個函式一產生輸出,應用程式就能將其注入目前的回應,無須等待該回應完成。等待中的智慧體可立即繼續執行,其他智慧體也能持續工作。當各智慧體在不同時間完成工作或要求使用工具時,這種方式可減少協調延遲,並避免額外的請求往返。
如果工作流程需要呼叫多個由伺服器端執行的工具(例如平行執行網頁搜尋),或只需一次請求且函式呼叫不多,HTTP 可能就已足夠。對大多數多智慧體工作流程而言,WebSocket 通常能降低延遲,並提升端對端效能。
透過 HTTP 執行函式呼叫
透過 WebSocket 執行函式呼叫
HTTP
這些範例需要使用提供測試版 Responses API 的測試版 SDK。使用 HTTP 串流時,請呼叫 client.beta.responses.create,並將 responses_multi_agent=v1 傳入 betas 引數,以啟用測試版型別與自動完成功能。在 Python 中新增型別註記時,請從 openai.types.beta 匯入測試版回應項目的型別。
用戶端程式碼範例:
from __future__ import annotations
import json
import sys
from openai import OpenAI
from openai.types.beta import BetaResponseOutputItem
client = OpenAI()
ROOT = "/root"
PROPOSALS = {
"alpha": {"estimated_weeks": 6, "risk": "medium"},
"beta": {"estimated_weeks": 8, "risk": "low"},
}
tools = [
{
"type": "function",
"name": "get_proposal",
"description": "Return details for a proposal that the agents should compare.",
"parameters": {
"type": "object",
"properties": {
"proposal": {
"type": "string",
"enum": ["alpha", "beta"],
}
},
"required": ["proposal"],
"additionalProperties": False,
},
"strict": True,
}
]
history = [
{
"role": "user",
"content": (
"Use two subagents, one for proposal alpha and one for proposal beta. "
"Have each call get_proposal, then compare their findings."
),
}
]
def agent_name(item: BetaResponseOutputItem) -> str:
return item.agent.agent_name if item.agent else ROOT
def render_to_user(delta: str) -> None:
print(delta, end="", flush=True)
def log_subagent_text(agent: str, delta: str) -> None:
print(f"[{agent}] {delta}", end="", file=sys.stderr, flush=True)
def process_tool_call(name: str, arguments: str) -> str:
if name != "get_proposal":
raise ValueError(f"Unknown tool: {name}")
parsed_arguments = json.loads(arguments)
return json.dumps(PROPOSALS[parsed_arguments["proposal"]])
while True:
output_items = []
pending_calls = []
item_agents: dict[int, str] = {}
stream = client.beta.responses.create(
model="gpt-6.1-sol",
input=history,
tools=tools,
store=False,
multi_agent={
"enabled": True,
"max_concurrent_subagents": 3,
},
stream=True,
betas=["responses_multi_agent=v1"],
)
for event in stream:
if event.type == "response.output_item.added":
item_agents[event.output_index] = agent_name(event.item)
elif event.type == "response.output_text.delta":
agent = item_agents.get(event.output_index, ROOT)
if agent == ROOT:
render_to_user(event.delta)
else:
log_subagent_text(agent, event.delta)
elif event.type == "response.output_item.done":
output_items.append(event.item)
if event.item.type == "function_call":
# Handle function calls from both the root agent and subagents.
pending_calls.append(event.item)
elif event.type == "response.completed":
print(f"\nUsage: {event.response.usage}", file=sys.stderr)
break
elif event.type in {
"error",
"response.failed",
"response.incomplete",
}:
raise RuntimeError(event)
history.extend(output_items)
for call in pending_calls:
history.append(
{
"type": "function_call_output",
"call_id": call.call_id,
"output": process_tool_call(call.name, call.arguments),
}
)
if not pending_calls:
break如果一個或多個智慧體呼叫了開發者自訂的函式,請執行每個待處理的呼叫,並建立包含所有呼叫輸出的接續請求。
WebSocket
在 WebSocket 模式下,當智慧體呼叫開發者自訂的函式時,請在應用程式中執行該函式,並透過 response.inject 事件將結果傳送至目前的回應。等待中的智慧體隨即可以繼續執行,無須等到整個多智慧體回應完成。
{
"type": "response.inject",
"response_id": "resp_123",
"input": [
{
"type": "function_call_output",
"call_id": "call_123",
"output": "{\"temperature\":72}"
}
]
}對於有效的 response.inject 請求,伺服器會傳回以下兩種事件之一:
response.inject.created:輸入已通過驗證,伺服器已接受注入請求。response.inject.failed:輸入未注入,請檢查error.code。
{
"type": "response.inject.created",
"sequence_number": 42,
"response_id": "resp_123"
}{
"type": "response.inject.failed",
"sequence_number": 43,
"response_id": "resp_123",
"input": [
{
"type": "function_call_output",
"call_id": "call_123",
"output": "{\"temperature\":72}"
}
],
"error": {
"code": "response_already_completed",
"message": "Response 'resp_123' has already completed."
}
}如果請求不符合 response.inject 的結構描述,伺服器會傳送狀態碼為 400 的一般錯誤,並關閉 WebSocket 連線。請先修正請求並建立新的 WebSocket 連線,再傳送下一個事件。
Python 測試版 SDK 透過 client.beta.responses.connect 提供 WebSocket 模式,TypeScript 測試版 SDK 則透過 ResponsesWS 提供此模式。請在連線標頭中傳入 OpenAI-Beta: responses_multi_agent=v1。與 HTTP 串流不同,WebSocket 連接器目前尚不接受 betas 引數。
請儲存 response.created 事件中的回應 ID,並在針對該回應傳送的每個 response.inject 事件中帶入此 ID。傳送要注入的項目後,請持續從 WebSocket 讀取事件,直到回應完成,且每次注入都已產生 response.inject.created 或 response.inject.failed 事件。
from __future__ import annotations
import json
from openai import OpenAI
client = OpenAI()
PROPOSALS = {
"alpha": {"estimated_weeks": 6, "risk": "medium"},
"beta": {"estimated_weeks": 8, "risk": "low"},
}
tools = [
{
"type": "function",
"name": "get_proposal",
"description": "Return details for a proposal that the agents should compare.",
"parameters": {
"type": "object",
"properties": {
"proposal": {
"type": "string",
"enum": ["alpha", "beta"],
}
},
"required": ["proposal"],
"additionalProperties": False,
},
"strict": True,
}
]
def process_tool_call(name: str, arguments: str) -> str:
if name != "get_proposal":
raise ValueError(f"Unknown tool: {name}")
parsed_arguments = json.loads(arguments)
return json.dumps(PROPOSALS[parsed_arguments["proposal"]])
def run_multi_agent(connection):
previous_response_id: str | None = None
pending_input: list[dict[str, object]] = [{"role": "user", "content": input()}]
while pending_input:
request = {
"type": "response.create",
"model": "gpt-6.1-sol",
"store": True,
"multi_agent": {"enabled": True},
"tools": tools,
"input": pending_input,
}
if previous_response_id is not None:
request["previous_response_id"] = previous_response_id
connection.send(request)
next_input: list[dict[str, object]] = []
completed_response = None
response_id: str | None = None
pending_injections = 0
for event in connection:
event_type = event.type
if event_type == "response.created":
response_id = event.response.id
elif event_type == "response.output_item.done":
item = event.item
if item.type == "function_call":
if response_id is None:
raise RuntimeError(
"Received a function call before response.created"
)
output = {
"type": "function_call_output",
"call_id": item.call_id,
"output": process_tool_call(item.name, item.arguments),
}
pending_injections += 1
connection.send(
{
"type": "response.inject",
"response_id": response_id,
"input": [output],
}
)
elif event_type == "response.inject.created":
pending_injections -= 1
elif event_type == "response.inject.failed":
pending_injections -= 1
if event.error.code != "response_already_completed":
raise RuntimeError(event.error)
next_input.extend(item.model_dump(mode="json") for item in event.input)
elif event_type == "response.completed":
completed_response = event.response
elif event_type in {
"error",
"response.failed",
"response.incomplete",
}:
raise RuntimeError(event)
if completed_response is not None and pending_injections == 0:
break
if completed_response is None:
raise RuntimeError("Connection ended before response.completed")
if pending_injections:
raise RuntimeError("Connection ended with unacknowledged tool results")
if not next_input:
return completed_response
previous_response_id = completed_response.id
pending_input = next_input
with client.beta.responses.connect(
extra_headers={"OpenAI-Beta": "responses_multi_agent=v1"},
) as connection:
response = run_multi_agent(connection)
print(
"".join(
part.text
for item in response.output
if (
item.type == "message"
and item.agent is not None
and item.agent.agent_name == "/root"
and item.phase == "final_answer"
)
for part in item.content
if part.type == "output_text"
)
)傳送 response.inject 事件後,請繼續從 WebSocket 讀取事件,並依照伺服器的確認結果處理:
response.inject.created:函式輸出已加入目前的回應。請繼續讀取該回應的事件。response.inject.failed且錯誤碼為response_already_completed:函式輸出尚未加入,回應就已完成。請取出失敗事件傳回的input,並將其放入新的response.create請求,以接續已完成的回應。response.inject.failed且錯誤碼為response_not_found:伺服器找不到response_id指定的回應。請確認使用的是從response.created收到的 ID。
一次多智慧體執行可能會跨越多個 Responses API 請求。使用 HTTP 時,如果智慧體呼叫了開發者自訂的函式,應用程式會執行該函式,並在新的 response.create 呼叫中提交輸出。使用 WebSocket 時,應用程式則會將函式輸出注入目前的回應。
新增的多智慧體輸出項目
多智慧體回應可包含以下三種新增的輸出項目:
multi_agent_call:記錄由伺服器端執行的多智慧體操作,例如spawn_agent。multi_agent_call_output:包含伺服器端執行操作後的結果。agent_message:攜帶一個智慧體傳給另一個智慧體的加密訊息。
call_id 欄位會將每個 multi_agent_call 與對應的 multi_agent_call_output 關聯起來。
每個項目也包含 agent 屬性。在 agent_message 中,agent.agent_name 用來識別接收訊息的智慧體。可使用 author 和 recipient 追蹤訊息的傳送方向。
當應用程式收到 multi_agent_call 時,請勿將其當成函式呼叫執行,也不要回傳結果。Responses API 會在伺服器端執行該操作,並傳回對應的 multi_agent_call_output。如果應用程式需要重播或追蹤執行過程,請保留這兩個項目。
[
{
"type": "multi_agent_call",
"id": "mac_123",
"call_id": "call_spawn_a",
"action": "spawn_agent",
"arguments": "{\"task_name\":\"agent_a\",\"fork_turns\":\"all\",\"message\":\"enc_...\"}",
"agent": { "agent_name": "/root" }
},
{
"type": "multi_agent_call_output",
"id": "maco_123",
"call_id": "call_spawn_a",
"action": "spawn_agent",
"output": [
{
"type": "output_text",
"text": "{\"task_name\":\"/root/agent_a\"}",
"annotations": [],
"logprobs": []
}
],
"agent": { "agent_name": "/root" }
},
{
"type": "agent_message",
"id": "amsg_123",
"author": "/root/agent_a",
"recipient": "/root",
"content": [
{
"type": "encrypted_content",
"encrypted_content": "enc_..."
}
],
"agent": { "agent_name": "/root" }
}
]歸屬於特定智慧體的 SSE 事件包含頂層的 agent 屬性。在 agent_message 事件中,agent.agent_name 用來識別接收訊息的智慧體。response.created 和 response.completed 等回應生命週期事件描述的是整體回應,因此不包含 agent 屬性。
{
"type": "response.output_item.done",
"agent": { "agent_name": "/root" },
"item": {
"type": "agent_message",
"id": "amsg_123",
"author": "/root/agent_a",
"recipient": "/root",
"content": [
{
"type": "encrypted_content",
"encrypted_content": "enc_..."
}
],
"agent": { "agent_name": "/root" }
}
}限制
- 壓縮:
- 啟用多智慧體功能時,不支援
/responses/compact端點。 - 當
multi_agent.enabled設為true時,即使請求未設定context_management,系統也會啟用伺服器端自動壓縮。系統會分別壓縮根智慧體與每個子代理程式的上下文,讓各自的上下文保持獨立。如需覆寫compact_threshold,使用者仍可在請求中明確設定context_management.compact_threshold。
- 啟用多智慧體功能時,不支援
- 啟用多智慧體功能時,不支援
reasoning.summary。 - 啟用多智慧體功能時,不支援
max_tool_calls。 max_concurrent_subagents的預設值為3,也是建議設定值。
提示詞撰寫指引
啟用多智慧體功能時,系統會自動將以下指示以一則新的開發者訊息附加到根智慧體和子代理程式各自的上下文中。這些指示無法編輯或移除。撰寫自己的開發者指示時,請以補充這些自動注入的指示為原則。
根智慧體
你是 `/root`,是團隊中的主要智慧體。團隊中的智慧體會協力達成使用者的目標。

你的回合開始時,你就是作用中的智慧體。
你可以啟動子代理程式來處理子任務,這些子代理程式也可以啟動自己的子代理程式。
團隊中所有智慧體的智慧與能力都相當,也都能使用同一組工具,包括你可以指派任務的智慧體。

你可以使用 `spawn_agent` 建立新的智慧體,使用 `followup_task` 將新任務指派給現有智慧體並啟動一個回合,也可以使用 `send_message` 將訊息傳給執行中的智慧體,而不啟動新回合。
子代理程式也可以啟動自己的子代理程式。
你可以透過 `fork_turns` 參數決定要將多少上下文傳給子代理程式。

你收到的訊息會採用以下格式:
```
Message Type: MESSAGE | FINAL_ANSWER
Task name: <recipient>
Sender: <author>
Payload:
<payload text>
```
這些訊息的收件對象可能標示為 to=/root。

共有 {max_concurrent_subagents + 1} 個可同時使用的執行名額,因此包含你在內,最多可有 {max_concurrent_subagents + 1} 個智慧體同時處於作用中狀態。
子代理程式
你是團隊中的一個智慧體,會與其他智慧體協力完成任務。

你可以啟動子代理程式來處理子任務,這些子代理程式也可以啟動自己的子代理程式。團隊中所有智慧體的智慧與能力都相當,也都能使用同一組工具,包括你可以指派任務的智慧體。

你可以使用 `spawn_agent` 建立新的智慧體,使用 `followup_task` 將新任務指派給現有智慧體並啟動一個回合,也可以使用 `send_message` 將訊息傳給執行中的智慧體。
子代理程式也可以啟動自己的子代理程式。

當你在 final 頻道中回應時,回應內容會立即傳回給你的上層智慧體。

你收到的訊息會採用以下格式:
```
Message Type: NEW_TASK | MESSAGE | FINAL_ANSWER
Task name: <recipient>
Sender: <author>
Payload:
<payload text>
```
你也可能看到訊息的收件對象標示為 to=/root/...,這表示你的識別路徑是 /root/...。

共有 {max_concurrent_subagents + 1} 個可同時使用的執行名額,因此包含你在內,最多可有 {max_concurrent_subagents + 1} 個智慧體同時處於作用中狀態。